Fairness aware AutoML on multiclass classification task
Existing report illustrations
The report images on this page are retained from earlier documentation;
they are not measurements from 1.4.0b1. Their original execution
environment is not recorded here. Re-run the example to measure predictive
performance and group metrics with your data and installed version.
Please run the example script to train AutoML on Drug dataset with Gender as sensitive feature.
python examples/scripts/multi_class_drug_fairness.py
Code from example script:
import pandas as pd
import numpy as np

from supervised import AutoML


df = pd.read_csv("tests/data/Drug/Drug_Consumption.csv")


X = df[df.columns[1:13]]

# convert to 3 classes
df = df.replace(
    {
        "Cannabis": {
            "CL0": "never_used",
            "CL1": "not_in_last_year",
            "CL2": "not_in_last_year",
            "CL3": "used_in_last_year",
            "CL4": "used_in_last_year",
            "CL5": "used_in_last_year",
            "CL6": "used_in_last_year",
        }
    }
)

y = df["Cannabis"]

# maybe should be
# The binary sensitive feature is education level (college degree or not).
# like in
# Fairness guarantee in multi-class classification
sensitive_features = df["Gender"]


automl = AutoML(
    algorithms=["Xgboost"],
    train_ensemble=True,
    start_random_models=3,
    hill_climbing_steps=3,
    top_models_to_improve=2,
    fairness_threshold=0.8,
    explain_level=1
)
automl.fit(X, y, sensitive_features=sensitive_features)
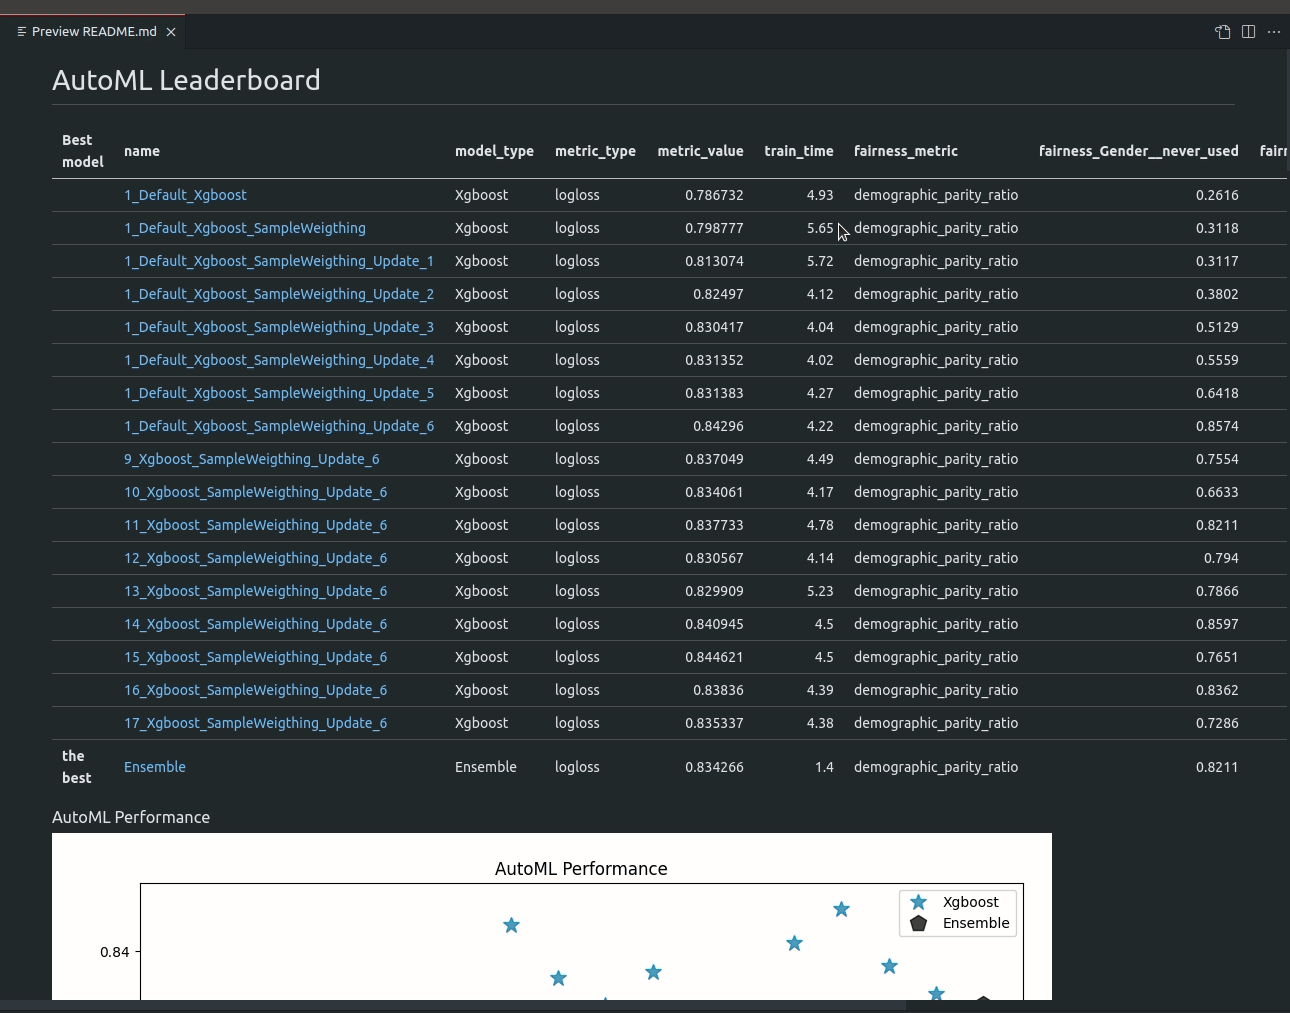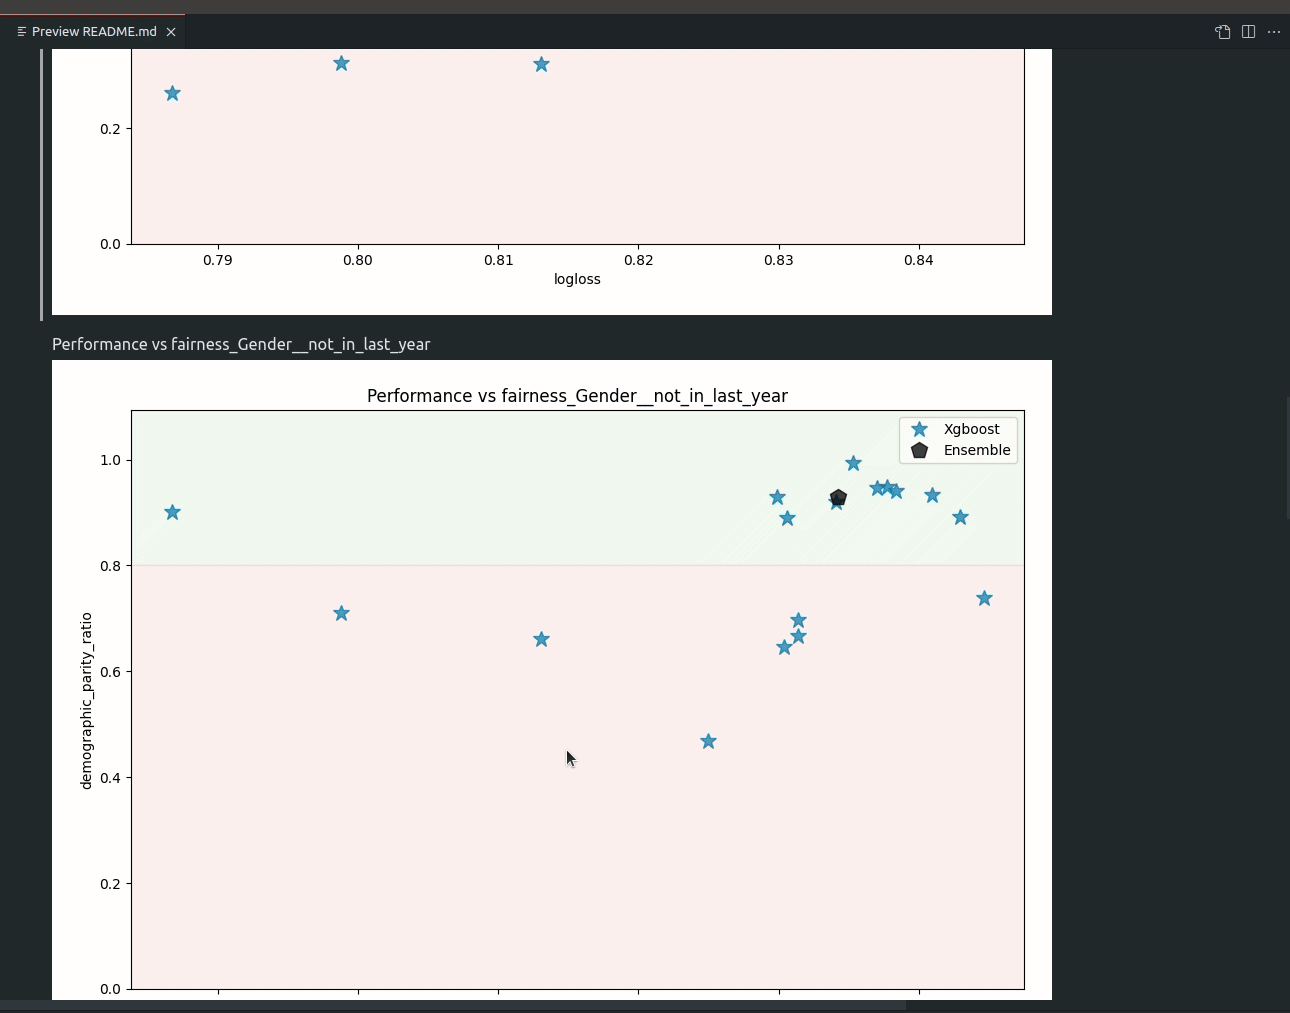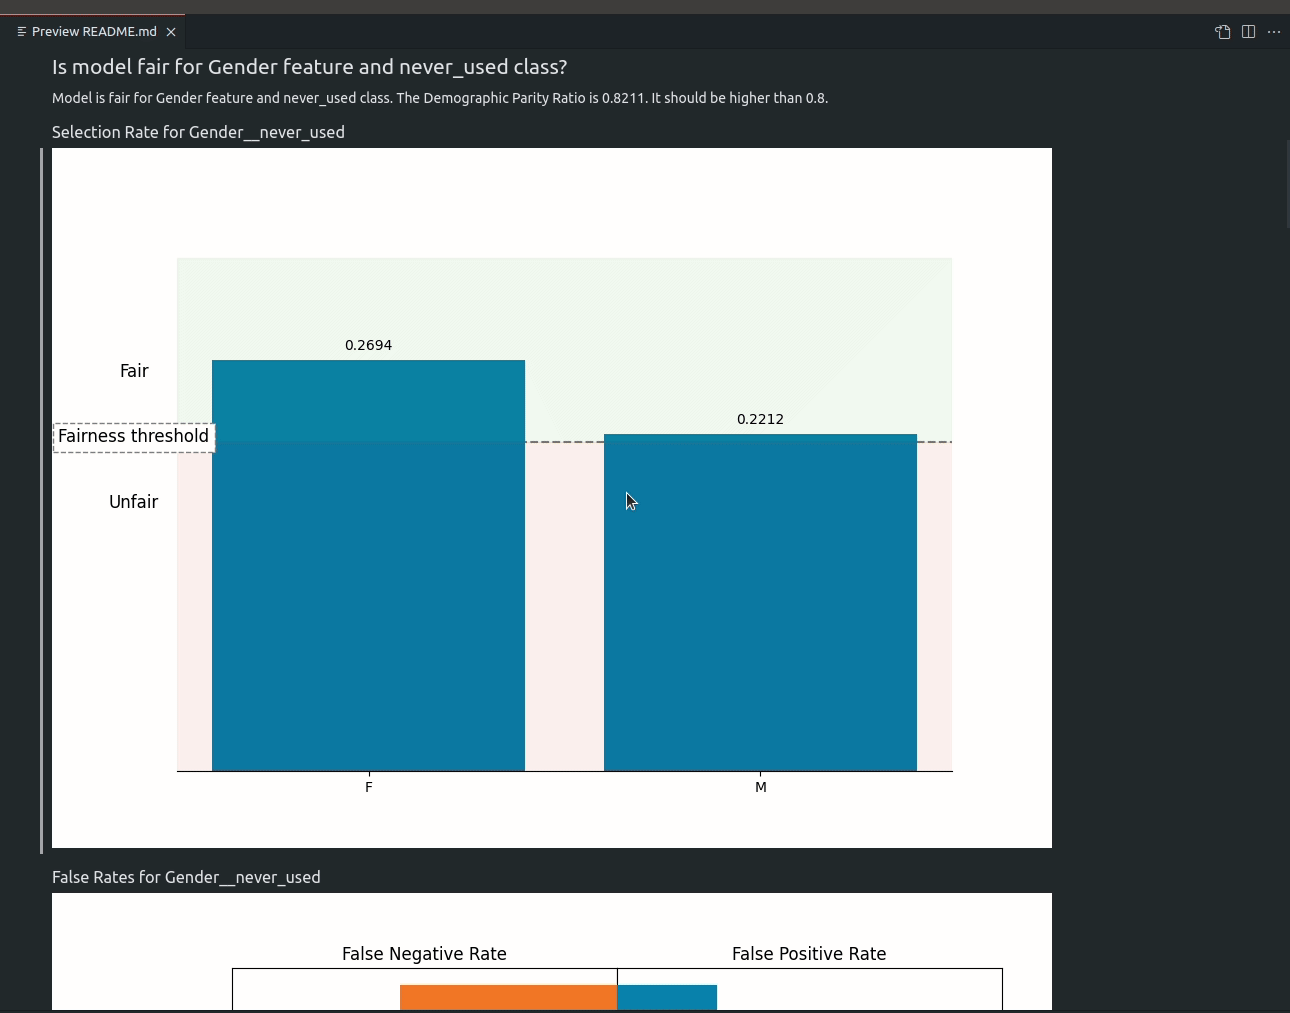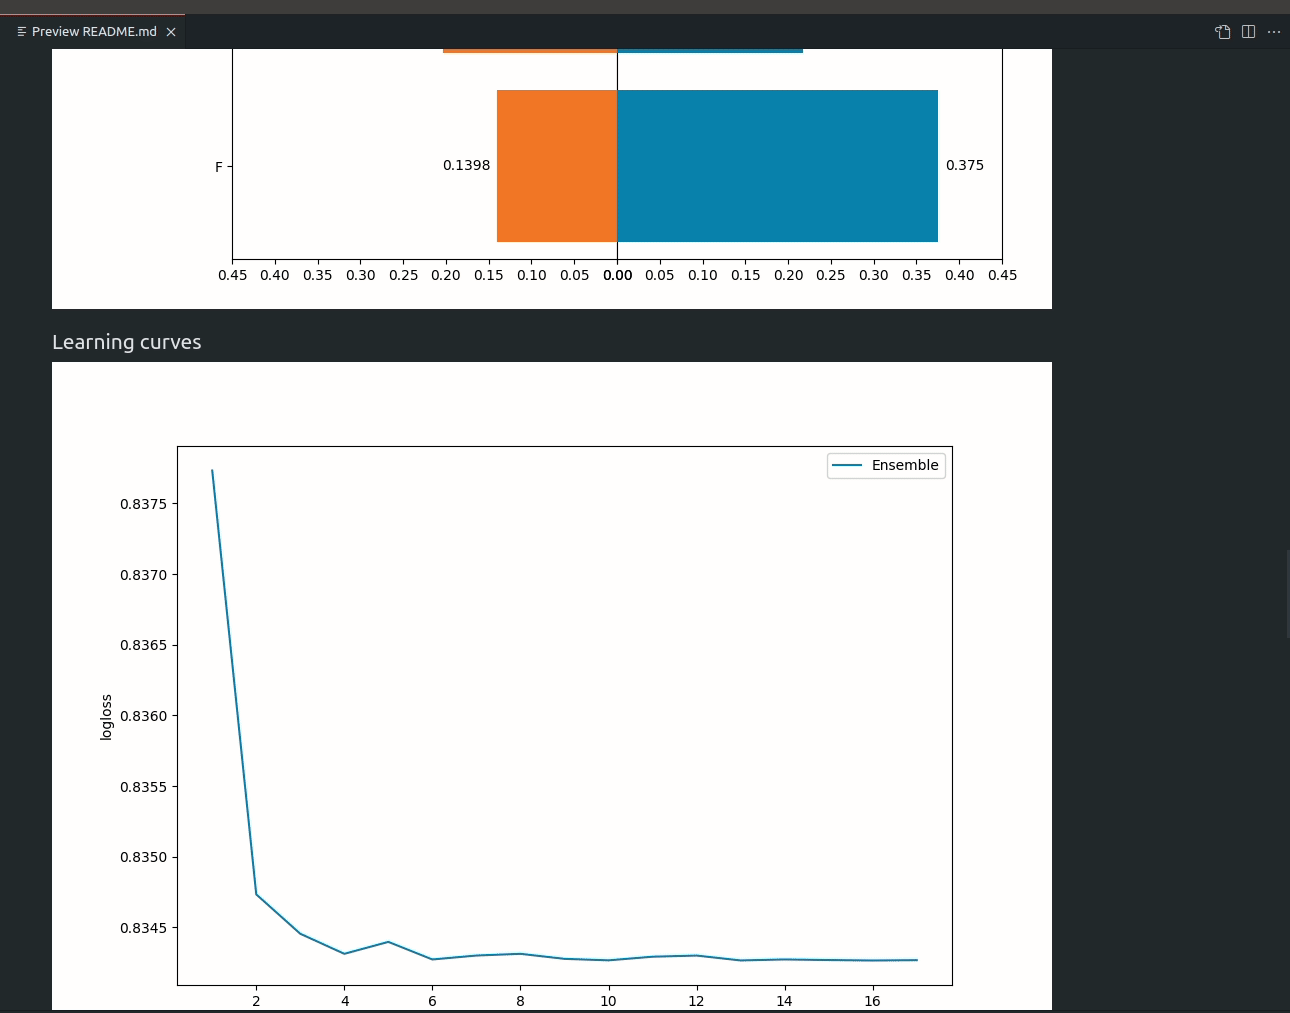
When using AutoML with fairness aware training for multiclass classification task, fairness metrics are reported for each class value. The AutoML leaderboard with fairness metrics for each class (please open the below image in the new tab for better quality).
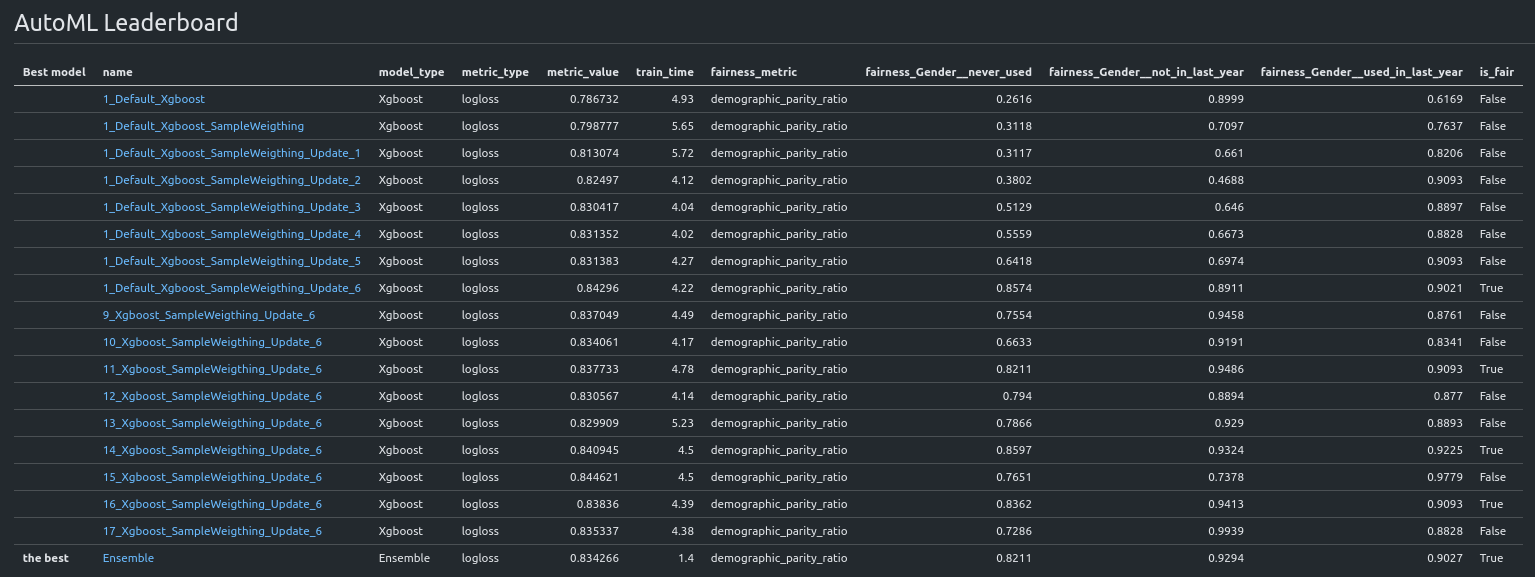
The report generated automatically after AutoML training: